
Chapter 05 of 12
API Test Data and Data-Driven Runs
How to make API tests deterministic, which means owning the data each run needs, cleaning up after it, and repeating one suite across many input rows.
Ask a team why their API suite is unreliable and the answer is almost never about assertions. It is about API test data. Somebody deleted the record the tests read, two suites created the same email address, or last week's run left rows behind that make this week's count assertion fail.
Test data management is the unglamorous half of API testing, and it quietly decides whether everything else in the suite can be trusted.
The four problems, and what solves each
| Problem | Symptom | What solves it |
|---|---|---|
| Tests need reference data | Hard-coded identifiers that break on every environment | Fixtures |
| Tests need state to exist before they run | A suite that passes only after somebody prepares the environment | Seeds |
| Runs leave the environment dirtier than they found it | Failures that only appear on the third run of the day | Snapshots and cleanup |
| One case needs to cover many inputs | Twelve near-identical cases nobody maintains | Data sets |
Fixtures are reference data, not test cases
A fixture is a named blob of structured data that tests refer to by path rather than by value. Instead of typing alice@example.com into eleven separate requests, you define the user once and reference the field wherever you need it.
alice:
  email: alice@example.com
  role: admin
bob:
  email: bob@example.com
  role: member
Two properties repay the indirection a fixture costs. The value exists in one place, so changing it changes every test at once. And the same data can feed more than tests, because a mock server that answers with the same records the tests assert on is a far better mock than one returning invented strings. The other half of that arrangement, which is where the rest of a mock response comes from, is covered in mock data worth testing against.
The trap is putting behaviour into fixtures. A fixture holding an expected response body couples every test to the shape of that body, and the contract already does that job. Keep fixtures to inputs and reference data.
Seeds set up and tear down
A seed is an ordered sequence of HTTP calls that runs around a suite, not inside it. The pre-run seed creates whatever the tests need, and the post-run seed removes it again afterwards.
Building setup out of the API's own endpoints instead of direct database writes is worth the small extra effort. Database seeding creates states the API itself could never produce, so your tests start passing against data that no real client could have caused. Going through the API keeps the setup honest and exercises the create path on the way.
Two details separate a seed that helps from one that becomes its own maintenance problem.
Capture what you create. A seed that creates a customer should capture the identifier the response returned, so the tests reference {{customerId}} rather than a value somebody pasted in.
Fail loudly on setup, quietly on cleanup. A failed pre-run seed means the tests would run against the wrong state, so the whole suite should abort. A failed post-run seed means the environment is untidy, and that deserves a warning, not a red run.
Snapshots reset a baseline
Some environments cannot be rebuilt from scratch for every run, either because the setup is long or because parts of it are shared. A snapshot is a recorded known-good state that can be restored before a run.
The important thing to understand about a snapshot is what it stores. It is not a database dump. It records which resources the setup created and how to remove them, so restoring means removing what is there and running the setup again to produce fresh data. That distinction matters for privacy, because the record holds identifiers and cleanup instructions and not the data itself.
Snapshots are the right tool when your suite mutates state and those mutations accumulate across runs. They are unnecessary overhead in a suite where every test already creates and cleans up its own data.
Data sets turn one case into many
Some coverage questions are entirely about input values. Whether the discount field accepts zero, whether the email validator rejects the awkward addresses, whether pagination behaves at its boundary.
Writing one case per value is how a suite grows into something nobody is willing to edit. A data set is a table attached to the suite instead, and the suite runs once per row with that row's values substituted in.
| password | expectedStatus | |
|---|---|---|
| valid@example.com | correct-horse | 200 |
| valid@example.com | wrong | 401 |
| not-an-email | correct-horse | 400 |
| (empty) | correct-horse | 400 |
Notice the third column. When the expected status is a column, one case asserts different outcomes for different rows, and that is what makes negative cases cheap. Without it you end up with a happy-path data set and a separate pile of hand-written failure cases.
Rows should be independent. A data-driven run that relies on row three having created something in row two is a workflow test written in the wrong shape, and it breaks the moment somebody reorders the table.
Choosing between a fixture and a data set
The two look similar on the surface, and they solve genuinely different problems.
| Use a fixture | Use a data set |
|---|---|
| The data is nested or structured | The data is flat, one row per case |
| Several tests, mocks or docs share it | The point is to repeat one suite across inputs |
| It describes what things are | It describes what to try |
A useful check is whether the data would still make sense if you deleted every test. Reference data would still make sense, while a table of boundary values would not.
In Routebase
Routebase has all four concepts natively, so there are no external setup scripts to keep in step with your specifications.
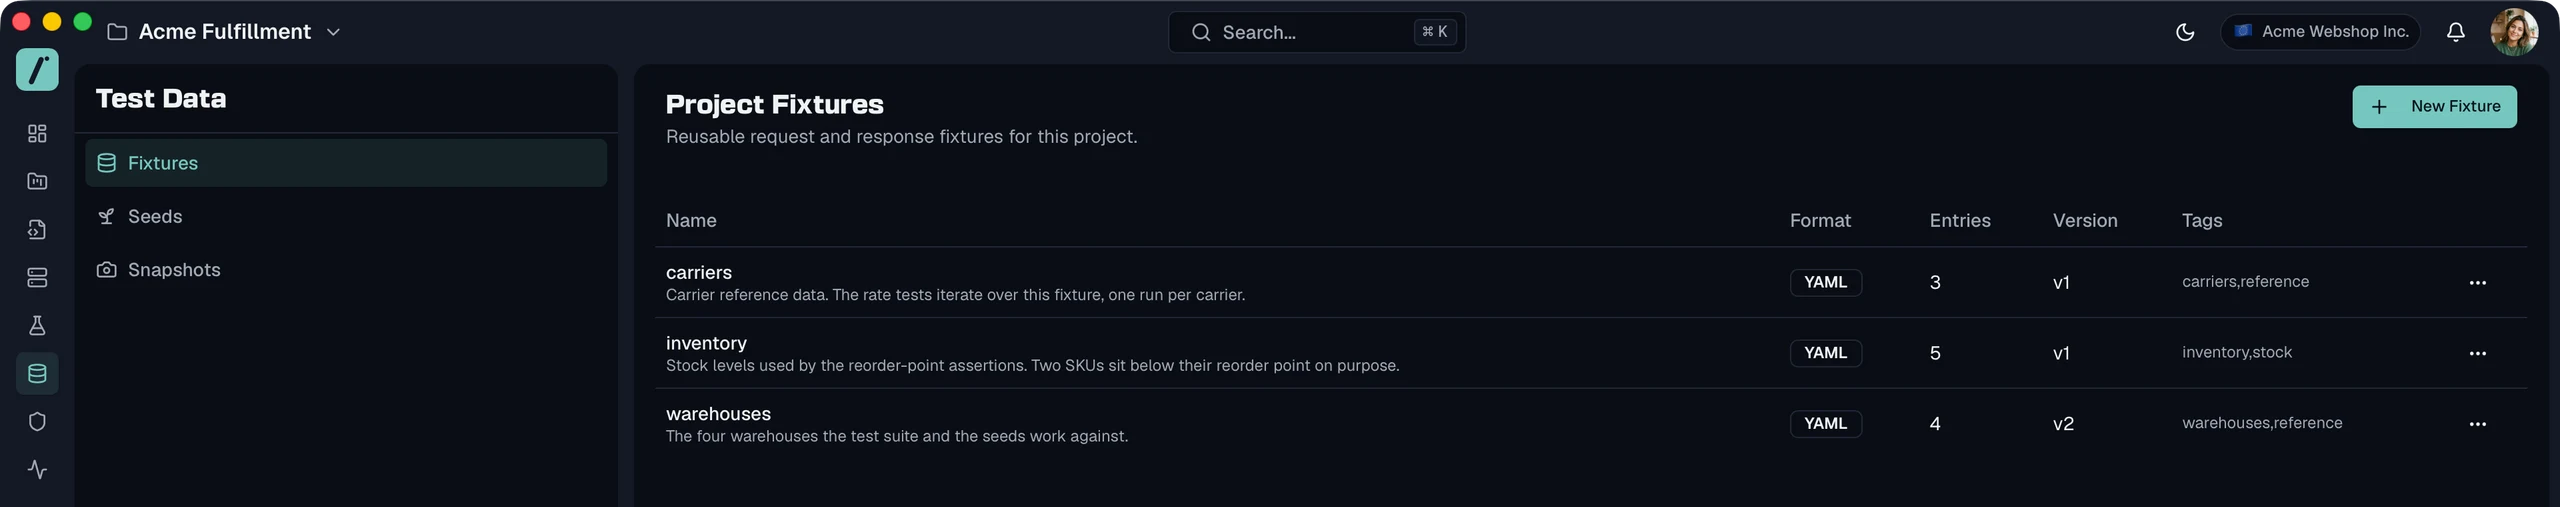
Fixtures are project-level structured data in a typed table or as raw YAML and JSON. A table-mode fixture links to one of your schemas, so its columns are the properties your API actually uses. Tests, seeds and mock rules reference them with {{fixture.users.alice.email}}, and pipes transform the value on the way, so {{fixture.users | where:role=admin | pluck:email | toJsonArray}} produces exactly the array you need. Every save is a version, and the history restores any earlier one.
Seeds are ordered step lists with four step types. Those are an HTTP request, a fixture loop that fires one request per entry, a delay, and a reference to an existing test case. Steps can be built straight from a spec endpoint, and captures pull values from the response into variables that later steps and the suite's cases can read. Dry Run resolves everything and returns the planned call list without touching your API.
Snapshots record a base seed's resources and the cleanup calls that undo them, so a restore removes what is there and re-runs the seed for fresh data. They store identifiers and cleanup instructions rather than personal data.
Data sets attach to a suite as columns and rows, imported from CSV, JSON or TSV or edited inline. Reference a column as {{data.email}} anywhere a template is accepted, including an assertion's expected value. Results break down per row, so a run reports something like eight of ten rows passed and lets you expand the two that did not.
Suite settings wire the pieces together with a pre-run seed, a post-run seed, a reset snapshot and a fixture scope. The full reference is in Test Data and Data-Driven Tests.
Frequently asked questions
What is test data management for APIs?
Test data management is the practice of making every run start from a state the test controls, rather than from whatever the shared environment happens to contain. It covers reusable reference data, setup and cleanup sequences that run around a suite, restore points that reset a known baseline, and tables of input rows that let one case cover many values. Without it a suite is only as reliable as the last person who cleaned up.
What is the difference between a fixture and a data set in API testing?
A fixture is one structured blob of reference data, often nested, that many tests, mocks and documents share. A data set is a flat table where each row drives one whole iteration of a suite. Use a fixture when the same reference data appears in several places, and use a data set when you want the same logic exercised across many inputs.
How do you keep API tests from interfering with each other?
Give each run the data it needs instead of relying on records somebody created by hand. Create resources in a setup step, reference them through variables the run captured, and remove them afterwards. Where creating everything is impractical, restore a recorded baseline before the run so the starting state is the same every time.
What is data-driven API testing?
Data-driven testing runs the same suite once for every row of a table, substituting each row's column values into the requests and the assertions. One login case then covers ten accounts, and one validation case covers every boundary value you care about. The expected outcome can be a column too, so a single case can assert 200 for valid rows and 400 for invalid ones.
Last reviewed by The Routebase Team.