
Chapter 01 of 12
Broken Object Level Authorization
API1:2023 is the flaw a single-user test suite cannot see, why proving it takes two identities from two tenants, and why 404 beats 403 on an object that is not yours.
An endpoint that reads an object has two jobs. It has to find the object, and it has to decide whether this caller is allowed to have it. The first job is in every codebase and the second one is optional in a way nobody intends.
OWASP lists this as API1:2023 Broken Object Level Authorization, and its references name CWE-639, Authorization Bypass Through User-Controlled Key, alongside CWE-285, Improper Authorization. It has led the list since the first edition, and the OWASP page rates both its prevalence and how easily it is found as high.
What it looks like from the outside
The request is ordinary in every respect. It carries a valid token, it matches the documented path, and the response matches the documented schema.
The only thing wrong with it is the identifier. A caller who holds a token for one account asks for an object that belongs to another, and the service answers, because the query filtered by object id and never by owner.
That is why the flaw survives code review so comfortably. The handler looks correct in isolation, and what is missing is a clause nobody wrote.
Why one identity proves nothing
This is a structural property of the test rather than a gap in anyone's diligence. If the only account in the run is the account that owns the data, then the ownership check and the missing ownership check produce identical output.
The method that works has two steps and needs two identities.
As user A   POST /orders          → 201, id = ord_a1
As user B   GET  /orders/ord_a1   → must be 404 or 403, never 200
Two details decide whether the result means anything.
Pick identities from different tenants. Two users inside one organisation may legitimately see each other's records, so a 200 there proves nothing and wastes the next hour. A user from a different customer entirely is the case that carries a real consequence.
Cover writes as well as reads. An update or a delete that takes an identifier has exactly the same exposure, and it costs more when it is wrong. The read case is simply the easiest one to demonstrate.
Prefer 404 over 403 on an object that is not yours
When the check does fire, the status code you return is a second decision, and it leaks information if you get it wrong.
A 403 says the object exists and you may not have it. That is a free existence oracle, so an attacker who can iterate identifiers learns which ones are real without ever reading a record. Returning 404 for both cases, meaning "does not exist" and "not yours", gives nothing away.
The trade-off is honest rather than free. A 404 is harder to debug for a legitimate caller who genuinely lost access, so log the real reason on your side and keep the response uninformative.
Fixing it where it cannot be forgotten
The reason this category keeps coming back is that the fix is usually written per handler, and handlers are added by people in a hurry.
The durable version pushes the check down to the layer that fetches data, so the ownership clause is part of every query by construction rather than by discipline. Whether that is a scoped repository, a row level policy in the database or a query filter applied by the framework depends on your stack. What matters is that a new endpoint inherits the check instead of needing it added.
OWASP's own guidance for the category is the same shape. It asks for an authorization mechanism that is relied on rather than reimplemented, and for the check to run in every function that receives a client-supplied identifier.
In Routebase
The two identities are personas, which are stored credential sets that a scanner can send. A persona carries any of the supported auth types, and Routebase rejects one with no credentials, because an identity that authenticates as nobody tests nothing.
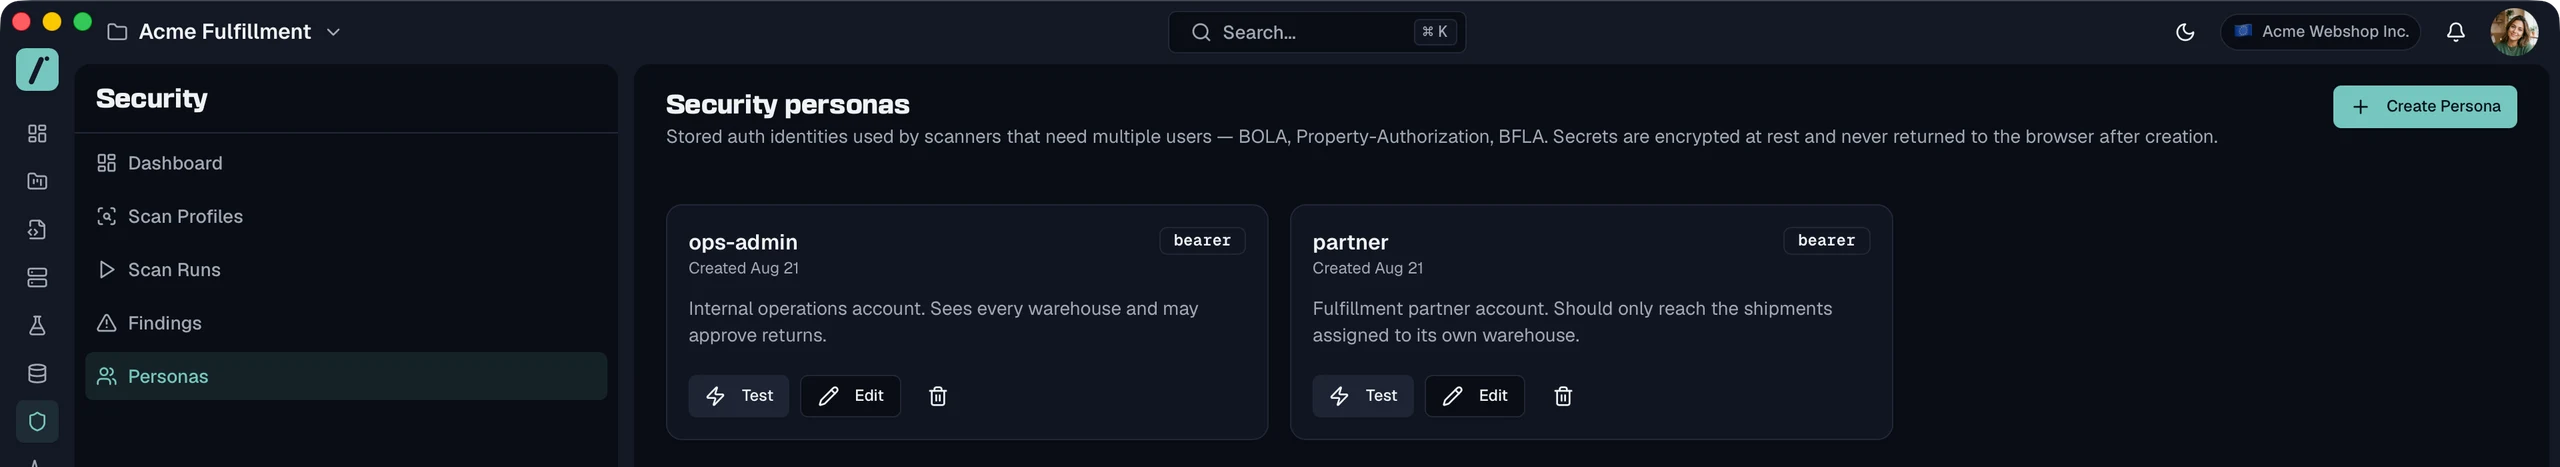
The api1-bola scanner runs the create-then-read method above. For each GET /resource/{id} endpoint it looks for a matching create call on the collection path. It then creates a resource as the first assigned persona, extracts the id from the response and reads it back as the second. A 2xx on that second call raises a Critical finding. Endpoints with no matching create call are skipped rather than guessed at, which keeps the false-positive rate down.
Those skipped endpoints are covered by a second scanner, api1-bola-enum, and it is deliberately more cautious because enumeration is weaker evidence. It abandons an endpoint whose identifiers are not sequentially readable, and it raises nothing when an unauthenticated request can already read the object. It also requires both personas to read the same distinct objects across several identifiers before it reports anything. It raises High at medium confidence rather than Critical, which is the honest grade for that evidence.
Both scanners need at least two personas assigned, and the profile editor will not save with fewer. Assign personas from different tenants for the reason above. See Security Personas and the Scanner Reference, and the next chapter for the other two authorization categories.
Frequently asked questions
What is broken object level authorization?
Broken object level authorization is an endpoint that checks whether you are logged in without checking whether the object you asked for belongs to you. Changing an identifier in the path or the body then returns somebody else's record. OWASP lists it as API1:2023, and its references name CWE-639, Authorization Bypass Through User-Controlled Key, and CWE-285, Improper Authorization.
What is BOLA and how is it different from IDOR?
BOLA is the name the OWASP API Security Top 10 gives the flaw, and IDOR, meaning insecure direct object reference, is the older name for the same failure in web applications. The mechanism is identical, because in both cases a user-controlled identifier reaches a data lookup that never asks who is allowed to see the result. The API case is more exposed, since the identifier is part of a documented contract rather than hidden behind a page.
Why can a normal test suite not find BOLA?
Because an ordinary suite authenticates as one identity, and an endpoint that returns everything to everybody looks perfect from inside a single account. Every assertion passes, the response matches the schema, and nothing in the run has a second identity to compare against. The flaw only becomes visible when a request made by one user is replayed by another.
Do random identifiers such as UUIDs fix BOLA?
No, they raise the cost of guessing and change nothing about the missing check. Identifiers leak through shared links, exports, logs, referrals and the other endpoints of your own API, and an attacker who holds one only needs the endpoint to answer it. Treat unguessable identifiers as a delay rather than a control, and put the ownership check in the query.
Last reviewed by The Routebase Team.